PostgreSQL BRIN Indexes: Tiny Indexes for Huge Tables
A PostgreSQL BRIN index stores min/max summaries per range of table pages, so it stays tiny and fast on ordered data like timestamps. How and when to use it.
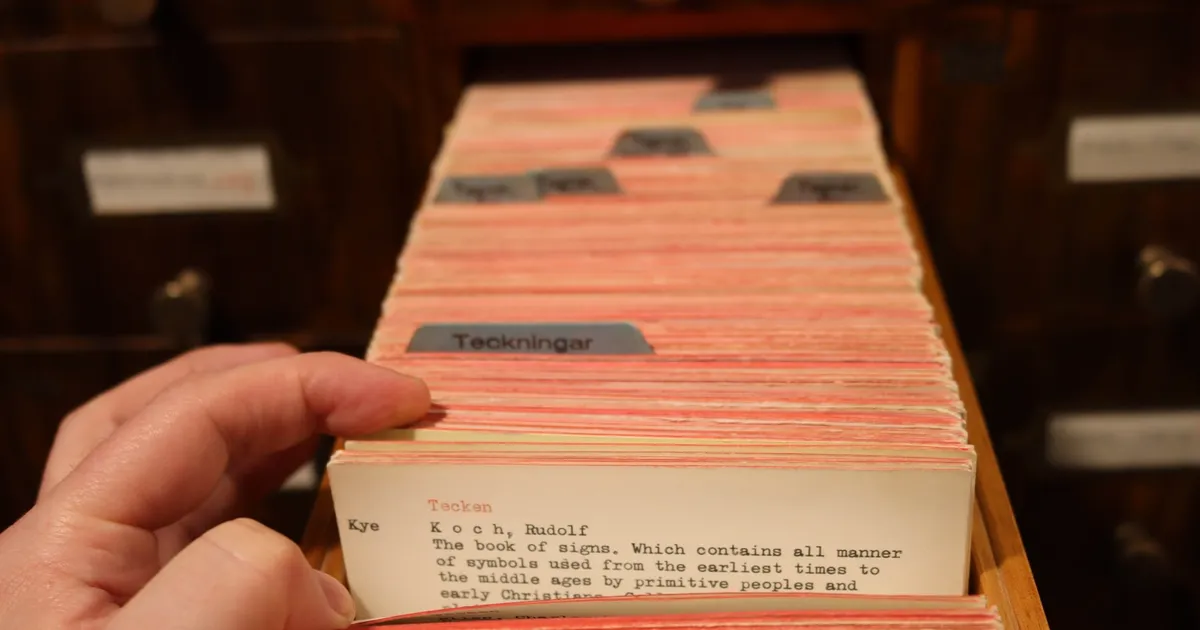
A BRIN index (Block Range INdex) is a PostgreSQL index type that stores a small summary, typically the minimum and maximum value, for each range of physical table pages instead of an entry for every row. Because it holds one summary per block range rather than one pointer per row, a BRIN index can be orders of magnitude smaller than a B-tree on the same column. The trade-off is that it only works well when the column’s values are correlated with the physical order of rows on disk, which is exactly the case for append-only data like event timestamps.
If you have a large table where new rows arrive in roughly increasing order and most queries filter on a range of that column, BRIN is often the right tool.
How a BRIN index works
PostgreSQL stores a table as a sequence of fixed-size pages. A BRIN index groups consecutive pages into block ranges, by default 128 pages per range, and records a summary for each range. With the default minmax operator class, that summary is just the lowest and highest value of the indexed column found anywhere in the range.
When a query asks for created_at between two dates, PostgreSQL walks the BRIN summaries and asks one question per range: could any row in this range match? If the range’s min and max fall entirely outside the query’s bounds, the whole range is skipped. If they overlap, every page in the range is a candidate.
The result is a lossy index. It never says “this row matches,” only “rows in these pages might match.” PostgreSQL builds a bitmap of candidate pages, reads them, and rechecks each row against the condition. In EXPLAIN output this shows up as a Bitmap Index Scan on the BRIN index feeding a Bitmap Heap Scan with a recheck condition and a count of rows removed by the recheck. Our guide to reading EXPLAIN ANALYZE covers those nodes in more detail.
Creating one
The syntax is the same as any other index, with USING brin:
CREATE INDEX events_created_at_brin
  ON events USING brin (created_at);
You can tune the range size with a storage parameter:
CREATE INDEX events_created_at_brin
  ON events USING brin (created_at)
  WITH (pages_per_range = 32);
Smaller ranges make the index more precise, because each summary covers fewer rows, at the cost of a larger index. Larger ranges make it even smaller but less selective. The default is a reasonable starting point; adjust it after measuring how many rows the recheck discards.
Why physical correlation matters
BRIN depends entirely on rows with similar values living near each other on disk. Consider two tables of the same size:
- An
eventstable where rows are inserted as they happen. Early pages hold early timestamps, later pages hold later ones. Each block range covers a narrow slice of time, so most ranges can be skipped for any date-range query. - A
userstable indexed onlast_login. Logins update rows all over the table, so any block range contains a mix of old and recent values. Each range’s min and max span nearly the whole domain, and BRIN cannot skip anything.
PostgreSQL tracks this property in its statistics. Check the correlation column in pg_stats for the table and column; values close to 1 or -1 mean physical order closely follows value order, which is where BRIN shines. Values near 0 mean BRIN will not help.
Heavy updates and deletes erode correlation over time, since updated row versions can land in free space anywhere in the table. BRIN fits best on append-mostly tables such as logs, sensor readings, audit trails, and other time-series workloads.
BRIN vs B-tree
| B-tree | BRIN | |
|---|---|---|
| Stores | One entry per row | One summary per block range |
| Size on large tables | Large, grows with row count | Very small |
| Precision | Exact row locations | Lossy, candidate pages only |
| Requires physical ordering | No | Yes, for good results |
| Point lookups | Excellent | Poor |
| Range scans on ordered data | Good | Good, with far less storage |
| Write overhead | Updated on every insert | Minimal |
| Supports uniqueness | Yes | No |
A B-tree remains the default for good reason: it handles equality lookups, sorting, uniqueness, and random data. BRIN is a specialist. On a huge append-only table, though, it can replace a B-tree that would otherwise consume a large share of memory and disk. For the broader landscape of index types, see our overview of PostgreSQL B-tree, GIN, and GiST indexes.
Keeping summaries up to date
New pages added at the end of the table are not summarized immediately. Until they are, BRIN treats them as unsummarized ranges that always have to be scanned. Summarization happens in a few ways:
- VACUUM summarizes any unsummarized ranges as part of its normal work, which is one more reason to keep vacuuming healthy.
- The
autosummarizestorage parameter asks autovacuum to summarize a range as soon as the previous one fills, rather than waiting for the next full vacuum. - Manual functions such as
brin_summarize_new_values()andbrin_summarize_range()let you summarize on demand, for example right after a bulk load.
Summaries are also widened, not narrowed, when rows change. If a value outside the existing min and max is inserted into a summarized range, the summary expands to include it. Deleting rows never shrinks a summary, so a table that sees many outliers inserted into old ranges gradually loses precision until those ranges are desummarized and rebuilt.
Other operator classes
minmax is the default, but it is not the only option:
minmax_multistores several smaller min/max intervals per range, which tolerates some out-of-order values without blowing up each summary.bloomstores a Bloom filter per range, useful for equality searches on columns that are not ordered at all.inclusionclasses summarize ranges of geometric types or network addresses with a bounding value that contains everything in the block range.
These are available in recent PostgreSQL releases; check the documentation for your version before relying on one.
When to choose BRIN
BRIN is a good fit when the table is large, rows arrive in an order that tracks the indexed column, queries filter on ranges of that column, and you care about index size or insert overhead. It is a poor fit for point lookups, random data, frequently updated columns, or anything requiring uniqueness. It also pairs well with partial indexes and table partitioning, which can restore locality for data that is not naturally ordered.
The takeaway
A BRIN index summarizes each range of table pages with a compact value such as min and max, letting PostgreSQL skip whole regions of a table that cannot match. It is tiny and cheap to maintain, but lossy and only effective when physical row order follows the indexed column. Check pg_stats correlation, keep summaries current with vacuum or autosummarize, and use it on large append-mostly tables where a B-tree would be needlessly heavy.
Tagged
Keep reading
 The Lycoris Team · · 5 min read
PostgreSQL pg_trgm: Fuzzy Search With Trigram Indexes
pg_trgm adds trigram similarity to PostgreSQL for typo-tolerant search and fast LIKE '%term%' queries. A step-by-step guide with GIN and GiST indexes.
The Lycoris Team · · 5 min read PostgreSQL Partial Indexes: Index Only the Rows You Need
A PostgreSQL partial index covers only rows matching a WHERE clause, making it smaller and faster. How partial indexes work, when to use them, and pitfalls.
 The Lycoris Team · · 5 min read
Clustered vs Non-Clustered Index Explained
A clustered index determines the physical row order on disk; a non-clustered index is a separate lookup structure. How they differ and when to use each.